Simple case
Note
In this section, indices have no particular meaning, they are just part of the name of a parameter.
A single input and output case is first studied. A single hidden layer is present. The input is \(x\) ; the ouput is \(a_j\) ; the target prediction is \(y\). The figure Simple case FNN shows this graph. The weights and biases are indicated over the edges. The dashed line symbolizes a comparison.
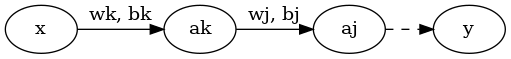
Simple case FNN
For regression, the cost \(J\) in equation (1) represents the agreement between prediction and a single target:
A value of the node \(a_j\) is obtained in two steps from the value of the previous node \(a_k\). First one obtains the intermediate variable \(z_j\) using the weight \(w_j\) and bias \(b_j\) of the edge leading to the node \(a_j\), then activation function \(\sigma(z_j)\) is used, see equations (2):
The derivation chain rule is applied to compute the gradient terms for the last layer, see equations (3) and (4):
To obtain the node \(a_k\) from node \(x\):
Similarly, the derivation chain rule is applied to compute the gradient terms for the second to last layer, see equations (6) and (7):
The method should seem straightforward. Start from the last node, compute \(\cfrac{\partial J}{\partial z_j}\) and save it for the second to last node calculation. Repeat the process for \(\cfrac{\partial J}{\partial z_k}\) and save it for the third to last node, and so on.
Note
The training is not performed using a single data \((x, y)\), but many. The gradient is obtained by averaging over the individual gradients.
Exercise (easy)
How would compute \(\cfrac{\partial a_j}{\partial x}\) (the derivative of the output with respect to the input)? What happens when only linear activations are used?
Correction
For a single hidden layer (but trivially generalizable):
with all \(\sigma'=1\), the network is just a linear operator, the derivative is just the product of the weights.